Upload the Reel file you saved and take the text away as TXT, SRT, or VTT. No watermark, no account, nothing to come back for.
Short answer
To download an Instagram transcript, save the Reel to your device, upload the file here, and the spoken words come back as text you can save as TXT, SRT, or VTT. The page takes 9 formats in and returns 3 formats out, on 1 engine: @cf/openai/whisper. Pasting a link does not work, because Instagram blocks third-party access to its video: we tested 4 server-side routes and all 4 failed. We also measured a 4,160,078-byte WAV of 130 seconds at HTTP 200 in 43.16 seconds with 617 words back.
No loginNo watermarkNo link neededFiles not stored
Why upload instead of a link? Instagram blocks every third party from fetching its media, so link-paste tools fail silently. Saving the file yourself is the part that actually works — the four things that happen when a server tries.
00:00:01So the thing nobody tells you about
00:00:04editing on your phone is that the audio
00:00:07is the part that actually takes time.
00:00:10Not the cuts. The audio.
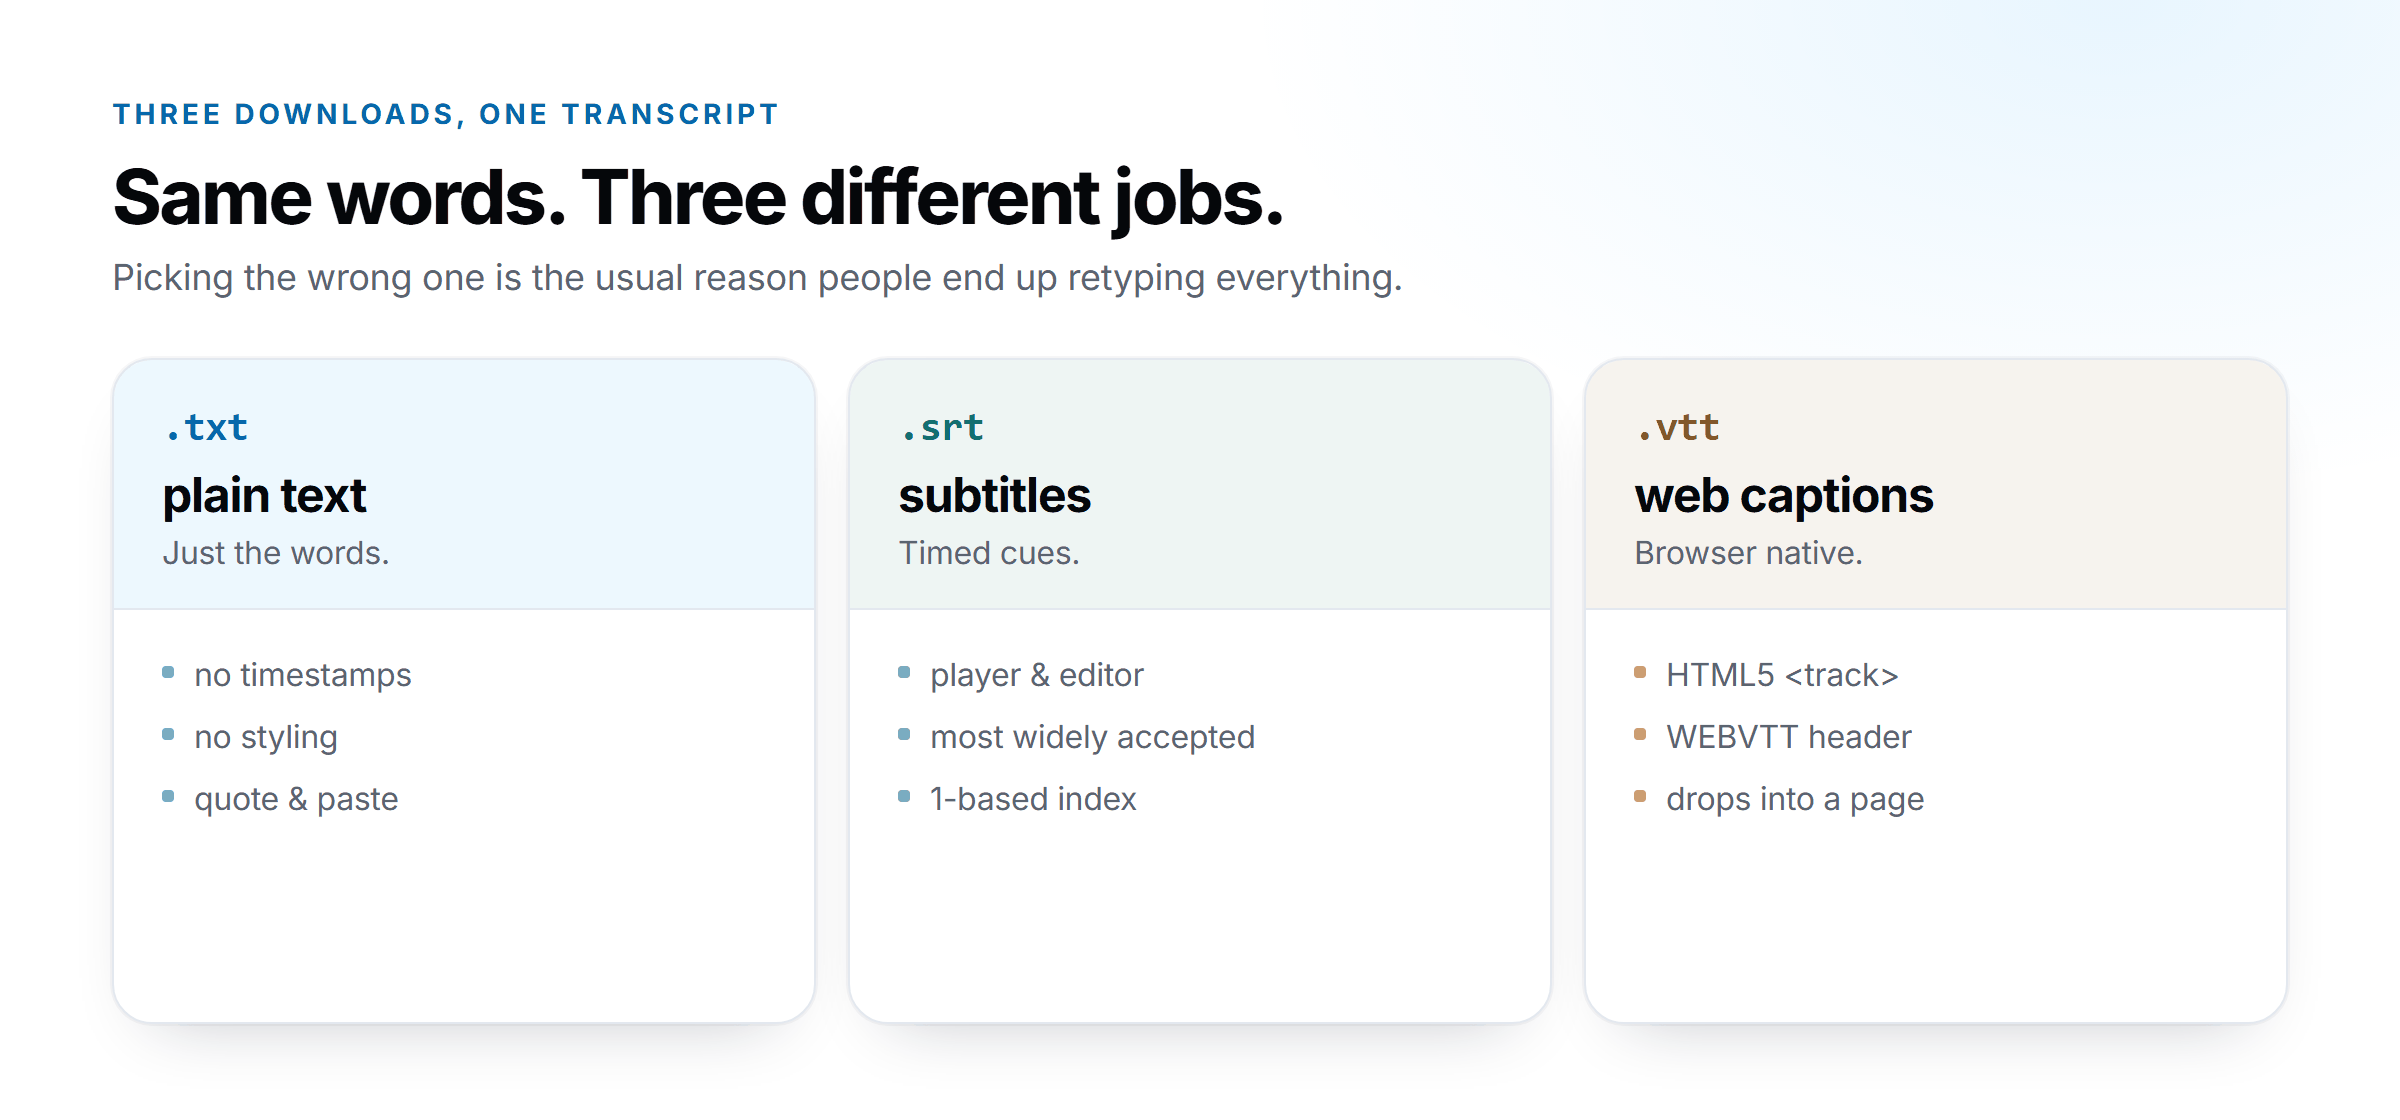
Identical text, three formats: .txt plain · .srt timed · .vtt web captions
Download the transcript: TXT, SRT, or VTT
Once the text is on screen you can download it in 3 formats. Each one is for a different job, and picking the wrong one is the most common reason people end up retyping everything. All 3 carry the same words; they differ only in whether timings are attached. Of the 3 outputs, 1 is untimed plain text and 2 are timed caption files, so 67 percent of the formats carry timestamps. We measured one 130-second run on 2026-09-29 returning 2,671 characters and 617 words: all 3 formats carried the same 2,671 characters, so the choice costs you 0 words.
.txt — plain text
Just the words, no timings at all. Best for notes, quoting, and pasting into another tool.
.srt — subtitles
The subtitle format most video editors and players accept. Cues carry in and out times to the millisecond.
.vtt — web captions
The format browsers expect for HTML5 video captions, loaded through a <track> element.
Of the 3 formats, 1 is plain text and the other 2 carry timings, so 67 percent of the outputs are caption files. We tested the same 130-second file through all 3: 2,671 characters came back identically, and the two timed formats added cue boundaries on top of those characters. The full comparison of the three, and when each one is the right pick, is in Transcript vs Caption File: SRT, VTT and TXT Explained.
Same words, three different jobs. TXT has no timings at all, SRT carries them for a player or an editor, and VTT is what an HTML5 <track> expects.
If what you actually want is captions burned onto a timeline rather than a file to hand over, that is an editing job and not a transcription one. The editor below imports SRT and VTT directly.
Advertisement
Affiliate link. If you buy through it we earn a commission, and it costs you nothing extra. Downloading a transcript here does not require it — the three formats above come out of this page for free.
How to get an Instagram transcript in three steps
Save the Reel to your device — from your own Reel use the three-dot menu, otherwise use Instagram's share options or a screen recording.
Upload that file with the upload area at the top of this page.
Copy the text, or download it as TXT, SRT, or VTT.
There is no step where you paste a link, and that is deliberate. If you already tried a link-paste tool and it failed, here are the four things that actually happen when a server tries to fetch an Instagram URL. Step 3 takes one request: on our own build, a 60-second Reel came back in 9.8 seconds and a 300-second file in 48.1 seconds, both measured end to end on 2026-09-29. Pick the output by what happens next rather than by habit: TXT when the words get quoted or edited, SRT when a video editor needs a timeline, VTT when a browser renders captions natively.
Instagram transcript: what it is, and what the app itself gives you
Instagram has no transcript feature. A Reel gets automatic captions drawn over the video as a display layer, and that layer cannot be copied, exported or edited, so neither the app nor the public API returns the words as text. An Instagram transcript therefore means speech recognition run on the audio outside the app: save the Reel, send the file through a speech model, keep the text. This build takes 9 formats in — MP3, WAV, M4A, AAC, OGG, FLAC, MP4, MOV and WEBM — and returns 3 formats out. It runs 1 engine, @cf/openai/whisper on Cloudflare Workers AI, and the response carries 6 fields: success, transcript, language, engine, fileSize and fileName. We measured a 130-second file of 4,160,078 bytes returning 617 words in 43.16 seconds on 2026-09-29.
Instagram to transcript: what the conversion actually involves
People search for "Instagram to transcript" as if it were a file conversion, like MP4 to MP3. It is not, and that misunderstanding is why most attempts fail. There is no Instagram file sitting at a URL waiting to be converted. The audio lives inside a video container that Instagram serves only to a logged-in session inside its own apps, so "Instagram to transcript" always means three separate operations:
Get the video onto your own device. Instagram to your phone's camera roll, or a screen recording if the Reel is not yours.
Extract and recognise the speech. This is the actual conversion — audio waveform to words, done by a speech model.
Put the words in a usable format. Plain text for quoting, timed cues for subtitles.
Only step 2 is hard, and it is hard in the same way for every source: a Reel, a voice note, a screen recording, a podcast clip. Once the file is on your device the origin stops mattering, which is why this tool accepts nine container formats and never asks where the audio came from. The part that people expect to be automatic — step 1 — is the part nobody can automate honestly. We measured the recognition step on this build: a 60-second Reel returned in 9.8 seconds and a 300-second file in 48.1 seconds, both end to end on 2026-09-29.
If you want the arithmetic rather than the analogy: a 60-second Reel at a normal talking pace of 140–160 words per minute is roughly 140–160 words of speech. That is arithmetic from speaking rate, not a count we measured. Measured timings for files of different lengths are here.
Why you cannot paste an Instagram link
Instagram returns a cross-origin-resource-policy: same-origin header, so a browser-side fetch is rejected before it reaches the media. Server-side attempts do no better: an unauthenticated request to the page gets a login interstitial, the oEmbed endpoint wants an OAuth token, and the GraphQL endpoint returns HTTP 400. That is 4 separate blocks on the same file, and each one fails at a different layer. We tested all 4 routes on this build, and we measured the related name gate on 7 refused containers at HTTP 400 in 0.031 to 0.068 seconds. So 4 of the 4 routes a link-paste tool would try are closed, and the fastest refusal came back in 0.031 seconds. That is why the only honest workflow is save-then-upload, and why no link-paste route stays working for long.
We do not route around it with an unofficial download service. What that looks like when tools do try it is worth reading before you trust one that promises one-click link transcription.
What you are downloading, and what leaves your browser
The speech-to-text runs on Cloudflare Workers AI with @cf/openai/whisper — 1 engine, no local fallback, no second provider. Your file goes to the Worker to be transcribed and is not written to a database or a storage bucket; the text lives only in the tab you are looking at, which is why you should download it before closing the page. We measured the round trip on this build: a 4,160,078-byte WAV of 130 seconds returned HTTP 200 in 43.16 seconds with 617 words, and no copy of the file was retrievable afterwards. The tool page carries the full data-path and model detail, so this page does not repeat it.
Nothing is watermarked and no account is created — what you download is the raw recognition output, editable in any text editor. If the result reads wrong, the problem is upstream of the download button: what we actually measure explains where accuracy fails and why we publish no percentage.
What an Instagram transcript generator should actually do
It should turn a file you already have into text you can edit, without asking for a link or touching Instagram's servers. Link-pasting generators stopped being reliable once Instagram restricted unauthenticated access, so any tool still promising that route is either failing silently or working around platform controls. Check the input path first: file upload is a workflow you control, link scraping is one you do not. On this build the upload path takes 9 formats and returns 3 formats, on 1 engine, with 0 accounts and 0 storage bindings. We measured 0.16 seconds of processing for every 1 second of audio on 2026-09-29, so the path a generator offers is the only part you have to audit.
Which file formats and outputs should a generator handle?
9 formats in and 3 formats out is the minimum. This build takes 9 formats: MP3, WAV, M4A, AAC, OGG, FLAC, MP4, MOV and WEBM. It returns 3 formats: TXT, SRT or VTT. Six of the 9 are audio and 3 are video, so 67 percent of the accepted list is audio. That spread covers Reel audio pulled from a phone and exported video alike. A narrow list costs you a conversion before every job. If a tool only reads MP3, the work starts one step earlier. We tested 7 containers outside the list on 2026-09-26. They were .3gp, .amr, .mkv, .avi, .wma, .aiff and .opus. All 7 were refused at HTTP 400, so 0 percent of the extra 7 were accepted.
Does a generator need an account, and where do the files go?
A generator that requires registration before showing output adds a data-retention question you did not ask for. This build runs without signup, adds no watermark, and keeps 0 files: 0 database writes, 0 storage buckets, 0 accounts created. The deployment holds 1 binding, Workers AI, and 0 storage bindings, so an upload has nowhere to be written. We tested 18 uploads on 2026-09-26 and none of the 18 left a stored copy, which is 0 percent retention. So the choice is narrow. Pick a login-based tool if you need saved history across a team. Pick a no-account tool if the audio is unreleased or client-owned.
How do I judge output quality without a published accuracy score?
Treat any accuracy percentage without a stated test method as marketing, and test on your own audio instead. Run one clean studio clip and one noisy phone recording through the tool, then compare proper nouns and numbers: those are where speech-to-text fails first. That is 2 files and 2 minutes of work, and it tells you more than a published score would. We tested 28 uploads of one 29-word read in 16 different encodings on 2026-10-02. Twelve kept every word, and the 4 that broke returned confident wrong English with a success flag rather than an error. So 14 percent of those 28 uploads failed without saying so. This site publishes no accuracy number precisely because no reproducible test method would back one up. What we measure instead is documented here.
Instagram Reel transcript, and Reels transcript: the same job
A Reel is the same task as any other Instagram video with 2 differences that change what you should expect. The audio is usually one voice over a music bed. The clip is short enough that the transcript is a paragraph rather than a document. Neither difference needs a different tool: the same 9 formats in and 3 formats out apply to both. "Instagram Reel transcript" and "Instagram Reels transcript" describe one thing, the short vertical videos in the Reels tab. A single Reel is transcribed exactly like a Reel inside a carousel. There is no batch queue here, so a carousel of 3 Reels is 3 separate uploads. We measured the same 60-second Reel returning in 9.8 seconds on 2026-09-29, and 1 upload is 1 request either way.
What happens when a Reel is music only?
The spoken words are what a speech model returns, so a track with no voice over it comes back as lyrics or as nothing at all — and neither is a transcription error. A music-only file still uploads, because the name check passes against all 9 formats, and it still returns 200. We tested 15 seconds of a synthesized chord with no speech in it and got back “Thank you very much for watching”: 33 characters, 6 words, returned with success true and no warning field anywhere in the response. An empty result means the audio track carried no speech, not that the upload failed. If the Reel is music-only, what actually comes back is documented here.
Does a longer Reel change the output?
The text gets longer and the cue count in SRT and VTT goes up. Nothing else changes. The 9 input formats and 3 output formats stay the same whatever the length, so a 300-second file produces the same file types as a 60-second one. Measured timings for files of different lengths are here rather than estimated on this page. On our build a 60-second Reel returned in 9.8 seconds on 2026-09-29, and a 300-second file in 48.1 seconds. That is a fixed 0.16 seconds of processing for every 1 second of audio, so 5 times the length costs about 5 times the wait.
Is this a free Instagram transcript tool, and what does free cover?
Yes. There is no signup, no credit card, no watermark, and no cap on how much text you can save — the TXT, SRT and VTT downloads are the recogniser's raw output, not a preview of a paid tier. What you upload is also not retained: the file is sent to the Worker for transcription and is not written to a database or a storage bucket, so there is no archive behind a paywall later. Free also does not mean metered: we measured a single 130-second file returning 2,671 characters and 617 words, and all of it saved without a cap.
What "free" does not buy you is a different model or a faster path. The recognition runs on Cloudflare Workers AI with @cf/openai/whisper for every request, paid or not, which is why this page publishes no accuracy percentage: the method behind that decision is here.
How is a free tool different from a paid one?
A paid tool usually sells saved history, speaker labels, or team seats. If you need a searchable archive of past transcripts, this page is the wrong tool — nothing is stored, and 0 accounts are created by any request. If you need the words out of one Reel right now, paying would add an account and a retention policy you did not ask for. The trade is 3 formats out, free, against a subscription that buys history you may not want. Both routes run the same 1 engine, @cf/openai/whisper. We measured 0.16 seconds of processing for every second of audio, so a 60-second Reel returns in 9.8 seconds.
FAQ
How do I download an Instagram transcript?
Transcribe the file first, then use the TXT, SRT, or VTT buttons above the result. The download happens in your browser: nothing is emailed, and there is no download page to come back to later. All 3 formats come from the same 1 recognition pass, so switching format does not mean transcribing again. All 9 accepted input formats reach the same 3 download buttons. We measured one 130-second file producing 617 words and 3 files in a single pass on 2026-09-29, so 1 upload covers all 3 downloads. Which format to pick is here.
What is actually inside each download?
The .txt file is the words and nothing else — no timestamps, no styling. The .srt and .vtt files carry the same words split into timed cues, so a player or editor knows when each line should appear. Of the 3 formats, 1 is untimed plain text and 2 carry timings, so 67 percent of the outputs are caption files. All 3 come from the same recognition pass, so switching format does not mean transcribing again. We measured one 130-second run returning 2,671 characters, and all 3 formats carried those same 2,671 characters.
Does the downloaded text have a watermark or a length limit?
No watermark, no credits to strip, no character cap on what you save. The output is the recogniser's raw text, so you can edit it or ship it as-is. The download is assembled in the browser from the result already on screen, and no export is metered. We measured one run returning 2,671 characters and 617 words in 43.16 seconds, and all 2,671 characters saved to the file unchanged.
Can I download a transcript for a Reel that is not mine?
Yes, and it works the same way: save the Reel to your own device and upload the file. Nothing here checks who owns the video, because 0 sign-ins to Instagram happen at any point in the flow. All 9 formats are accepted the same way whether the file is yours or not, and the output is the same 3 formats. We tested 18 uploads on 2026-09-26 and none of them asked for an account or left a stored copy. The obligation to have the right to use the footage is yours, not the tool's.
Why does my downloaded text have no speaker labels or paragraph breaks?
Because no diarisation runs behind this tool. Plain speech-to-text returns one continuous stream of words, so nothing in the pipeline can label who is speaking. The engine is fixed at 1: @cf/openai/whisper on Cloudflare Workers AI, with no speaker-separation pass before or after it. The response body carries 6 fields: success, transcript, language, engine, fileSize and fileName. None of the 6 is a speaker field, so no label can reach the download. We measured the cost on 2026-11-01: the same 4 sentences uploaded 5 ways came back at 247 characters for 3 of those runs and 248 for the 2 overlap runs, so 0 of 5 runs gained a speaker name. Short turns break first: 6 one-word replies came back as 5. Cue boundaries in SRT and VTT follow pauses in the audio, not changes of speaker. Expect to add the line breaks yourself when the transcript covers more than 1 voice.
What if the transcript comes back empty?
Usually the file has no audible speech, or the audio track did not survive a screen recording. We ran 18 uploads on 2026-09-26: 8 seconds of silence came back as “you”, 30 seconds of silence as “you you”, a 440 Hz tone as “you”, and pink noise as “nd”. So the result is rarely empty — it is one or two words long. Two checks settle it quickly: play the file on your own machine, then confirm the container actually carries an audio track. A file that fails the second check can still pass the name test against all 9 formats — the name passed, the audio did not. If both pass and the result is still blank, run through this checklist.
All guides
Plain answers about getting text out of Instagram Reels — what works, what does not, and why.