Teams Transcript: What the VTT and the Audio Disagree About
Four files, one answer
A recorded Teams meeting leaves you a folder, not a file. Depending on how the export ran, you get an MP4, an M4A, and a VTT written by the transcription service. The VTT looks like the finished product because the words are already in it. It is the one file this endpoint will not take.
We built a 50.9-second recording with two speakers and exported it the way Teams does. That gave us four files. An MP4 with an embedded subtitle track. The same MP4 with the track stripped. An M4A pulled out of the audio stream. A VTT in each of the two styles the services write. Then we uploaded all five.
- MP4 with the caption track muxed in, 793,148 bytes: HTTP 200 in 5.75 seconds, 138 words, 738 characters.
- Same MP4 without the track, 792,322 bytes: 200 in 5.55 seconds, 138 words, 738 characters.
- M4A copied out of the video stream, 781,443 bytes: 200 in 5.45 seconds, 138 words, 738 characters.
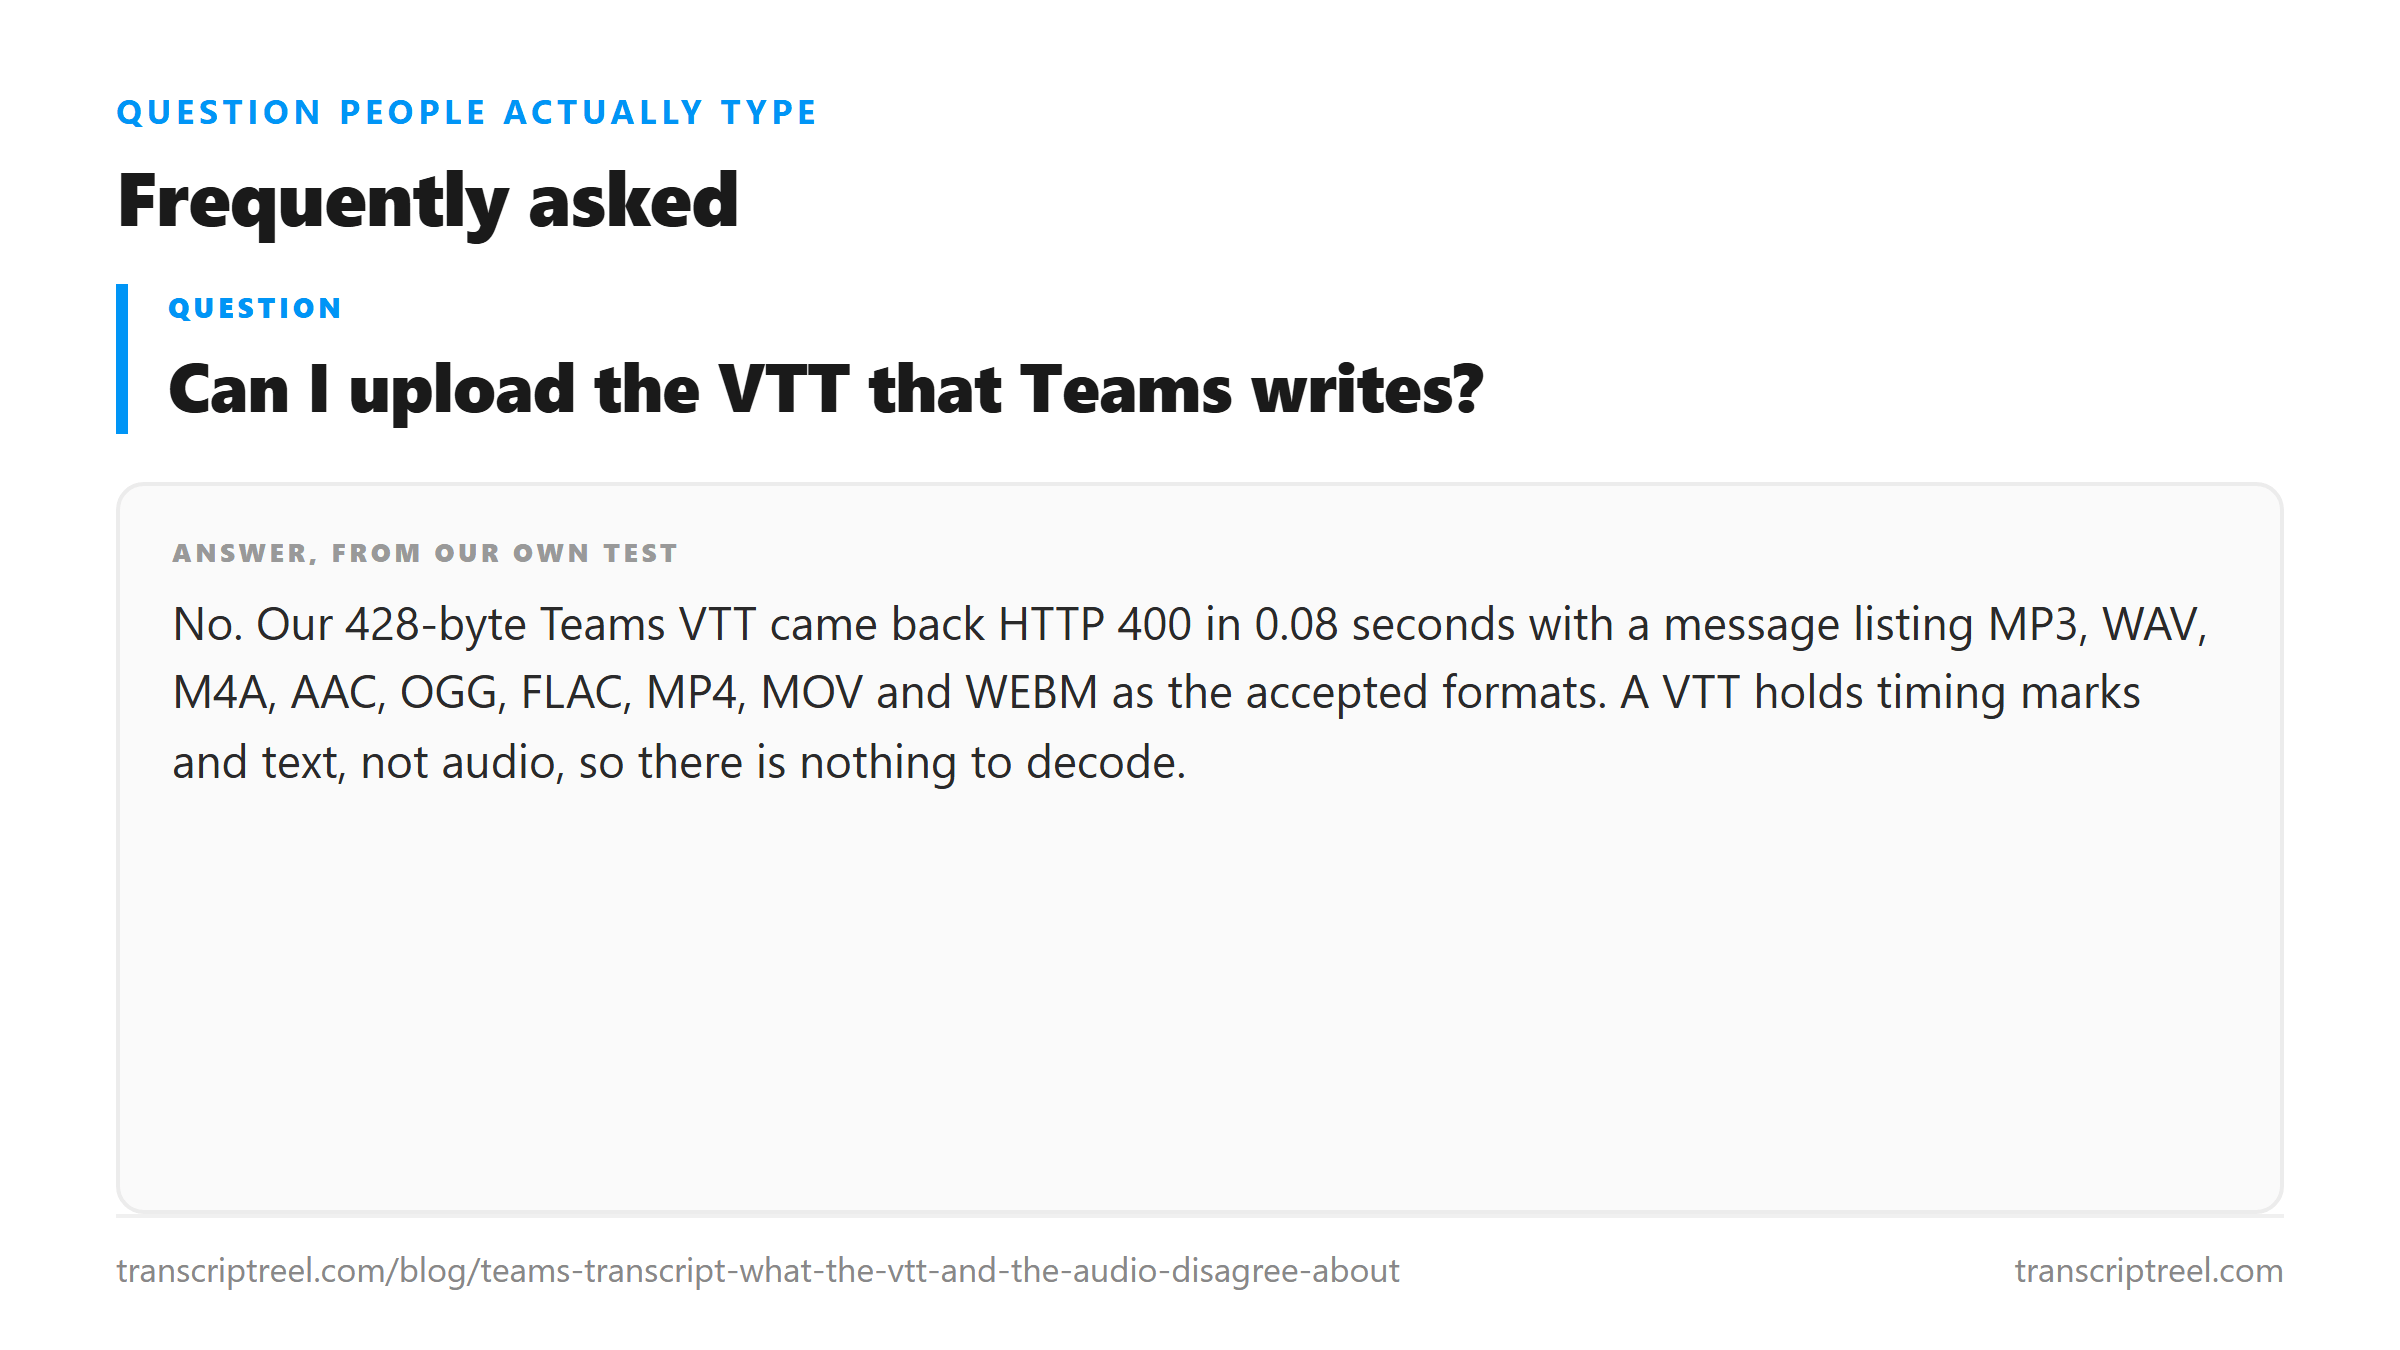
- Teams-style VTT, 428 bytes: 400 in 0.08 seconds, zero words.
- Zoom-style VTT, 296 bytes: 400 in 0.41 seconds on two runs, 0.06 on the third. Same bytes every time.
Four files, and three of them produce text that matches character for character. The container changed nothing. What changed was whether the request got past the door.
Why the VTT dies in a tenth of a second
The refusal timing is the evidence. A tenth of a second is not enough to upload 428 bytes, decode an audio stream that does not exist, and run a model over it. Nothing was transcribed. The request was rejected on the name of the extension.
The body says as much: unsupported file format, followed by the list of what it does accept - MP3, WAV, M4A, AAC, OGG, FLAC, MP4, MOV, WEBM. A VTT is a text file with timing marks in it. No audio stream, nothing to decode, and no rename creates one.
The Zoom-style file produced a strange spread: 0.41 seconds twice, then 0.06 on the third try, identical bytes each time. That is a queue, not a decision. If you are timing refusals to prove a point, three runs is the floor, and a slow refusal is not a near miss.
The two VTTs are not the same text file
Here is where Teams and Zoom actually part company, and it has nothing to do with audio. Both write WebVTT. They do not write the same WebVTT.
The Teams file puts a 36-character GUID on its own line above every cue, with a `/1-1` suffix, and wraps the spoken line in a `
Read both the lazy way and the same three cues produce very different amounts of text. Drop blank lines, drop the WEBVTT header, drop the lines with `-->`, join what is left.
- Teams: 314 characters, 38 words. Three GUID lines cost 123 characters of hex, and three voice tags cost another 37.
- Teams with markup and identifiers stripped: 154 characters, 29 words.
- Zoom: 185 characters, 35 words. Nothing to strip.
That 160-character gap is the whole difference between the two exports. A reader skips hexadecimal; a language model does not. Paste `0f1a2b3c-1111-4a4a-9c9c-000000000001` into a chat window and ask for a summary, and you have given it something to do with those digits.
The voice tags are worse, because they sit inside the sentence and look like content. `Okay, before we start` becomes `
The rule that follows is short. If you are going to treat a caption file as text, strip the cue identifiers and the voice tags first. Teams needs that step. Zoom does not.
The caption track inside the MP4 is never read
The MP4 is the case people ask about, because Teams can mux the VTT into the video as a subtitle stream. That stream has the words in it already. Does anything downstream look at them?
We put a deliberately wrong subtitle track into the MP4 - three cues about a purple bicycle, seventeen crates of oranges, and an elevator inspection - and uploaded it. The transcript came back with 138 words and no bicycles. Then we flagged that same stream as the default track and uploaded again. Still 138 words, still nothing from the subtitles.
So audio is the only input. The caption track rides along as dead weight, roughly a kilobyte in our file, and the recognizer never opens it. That answers a question people ask a lot: no, you cannot skip the transcription by shipping the subtitles inside the video.
It also means you do not need to strip the track first. Two files that differ by 826 bytes and one subtitle stream returned text that matched character for character, 138 words each.
The copy that saves you a re-encode
If the folder is all you have, the route is one command. It moves the audio packets instead of decoding them, so nothing about the speech changes.
- `ffmpeg -i meeting.mp4 -vn -c:a copy meeting.m4a`. On our 793 KB file this produced a 781 KB M4A in well under a second.
- Upload the M4A. 200 in 5.45 seconds, 138 words, 738 characters.
- Keep the VTT open beside the result if you need speaker labels, because the audio carries none.
That last line is the trade you are making. The caption file knows who spoke - `Jane Doe` and `Raj Patel` in our sample, as tags in the Teams file and as inline prefixes in the Zoom one. The M4A does not know, and neither does the transcript that comes back from it. You get clean text with no attribution, or attributed text with markup you have to clean by hand.
One setting that does not matter: bitrate. We re-encoded the same recording at 24, 32, 64 and 128 kbps and uploaded all four. They returned 131 words each, with one character of difference between the lowest and the highest, and that character was a comma. Re-encoding a meeting to improve the text is time spent for nothing.
What the good file still gets wrong
The 138 words are not perfect. Read the output against the script and the errors cluster in two places, neither of them about containers.
- Spelled-out numbers turn into digits. `March 15, 2026` stays as written, but `forty seven` inside prose comes back as `47`.
- A web address loses its punctuation. `example.com` came back as `example dot com` in the file where the two sources were mixed at full level.
- The sentence is otherwise intact. That is the dangerous part - a wrong word in a clean sentence reads as correct.
None of that is fixed by choosing a better container, a higher bitrate, or a different export path. The words were already in the audio at that quality, and the recognizer read them the way it read them.
The number errors are the ones worth planning around. `March 15, 2026` survived intact because it was already written as digits in the script. `forty seven` did not - it came back as `47`, and the sentence around it reads correctly, so a proofreader skimming for meaning will pass it. If a figure matters, check it against the audio rather than against the flow of the paragraph.
Where the audio goes
The M4A is posted to /api/transcribe over TLS, processed once in memory, and dropped when the response returns. Nothing is stored, nothing trains on it, and there is no account. The two VTTs never got that far - they were refused at the extension check, so their bytes were never read as audio at all.
What to send, in one line
Send the audio. If the MP4 is all you have, copy the track out with `-c:a copy` and send that. If the VTT is all you have, you already own the words - what you lack is a file this endpoint will accept, and no rename fixes that.
Got a Reel you want as text? Get an Instagram transcript as TXT, SRT, or VTT →
Copying the audio out of a meeting MP4 is a track move, not a re-encode. Wondershare UniConverter does that on your own machine and writes the result at the sample rate the recorder used, so the 138 words here arrived unchanged. It does not transcribe - the words come back from this page.
FAQ
Can I upload the VTT that Teams writes?
No. Our 428-byte Teams VTT came back HTTP 400 in 0.08 seconds with a message listing MP3, WAV, M4A, AAC, OGG, FLAC, MP4, MOV and WEBM as the accepted formats. A VTT holds timing marks and text, not audio, so there is nothing to decode.
Does the caption track inside the MP4 get used?
It does not. We embedded three deliberately wrong cues about a bicycle and some oranges, uploaded the MP4, and got 138 words with no trace of either. Setting that subtitle stream as the default track changed nothing. Only the audio stream is read.
Why does the Teams VTT give me more text than the Zoom one?
Because of markup. For the same three cues, the Teams file produced 314 characters and 38 words against the Zoom file's 185 characters and 35 words. The extra 160 characters are 123 characters of GUID cue identifiers plus 37 characters of `
Is a higher bitrate M4A worth making before uploading?
Not for this endpoint. We encoded the same recording at 24, 32, 64 and 128 kbps and got 131 words from every one. The only difference across the four was a single comma. The recognizer is not starved of detail at 24 kbps on clean speech.