What You Get When You Download an Instagram Story
What actually lands in your camera roll
A Story is a 15-second slot. Whatever app or site you use to save one hands you a single MP4 at 1080x1920, already muxed, with the audio baked in. There is no separate audio file, no sidecar, no caption track. If the Story was a still image with a music sticker, you may get a file with a silent audio track. You may also get one with no audio track at all. That difference decides everything that happens next.
Four bitrates, one set of words
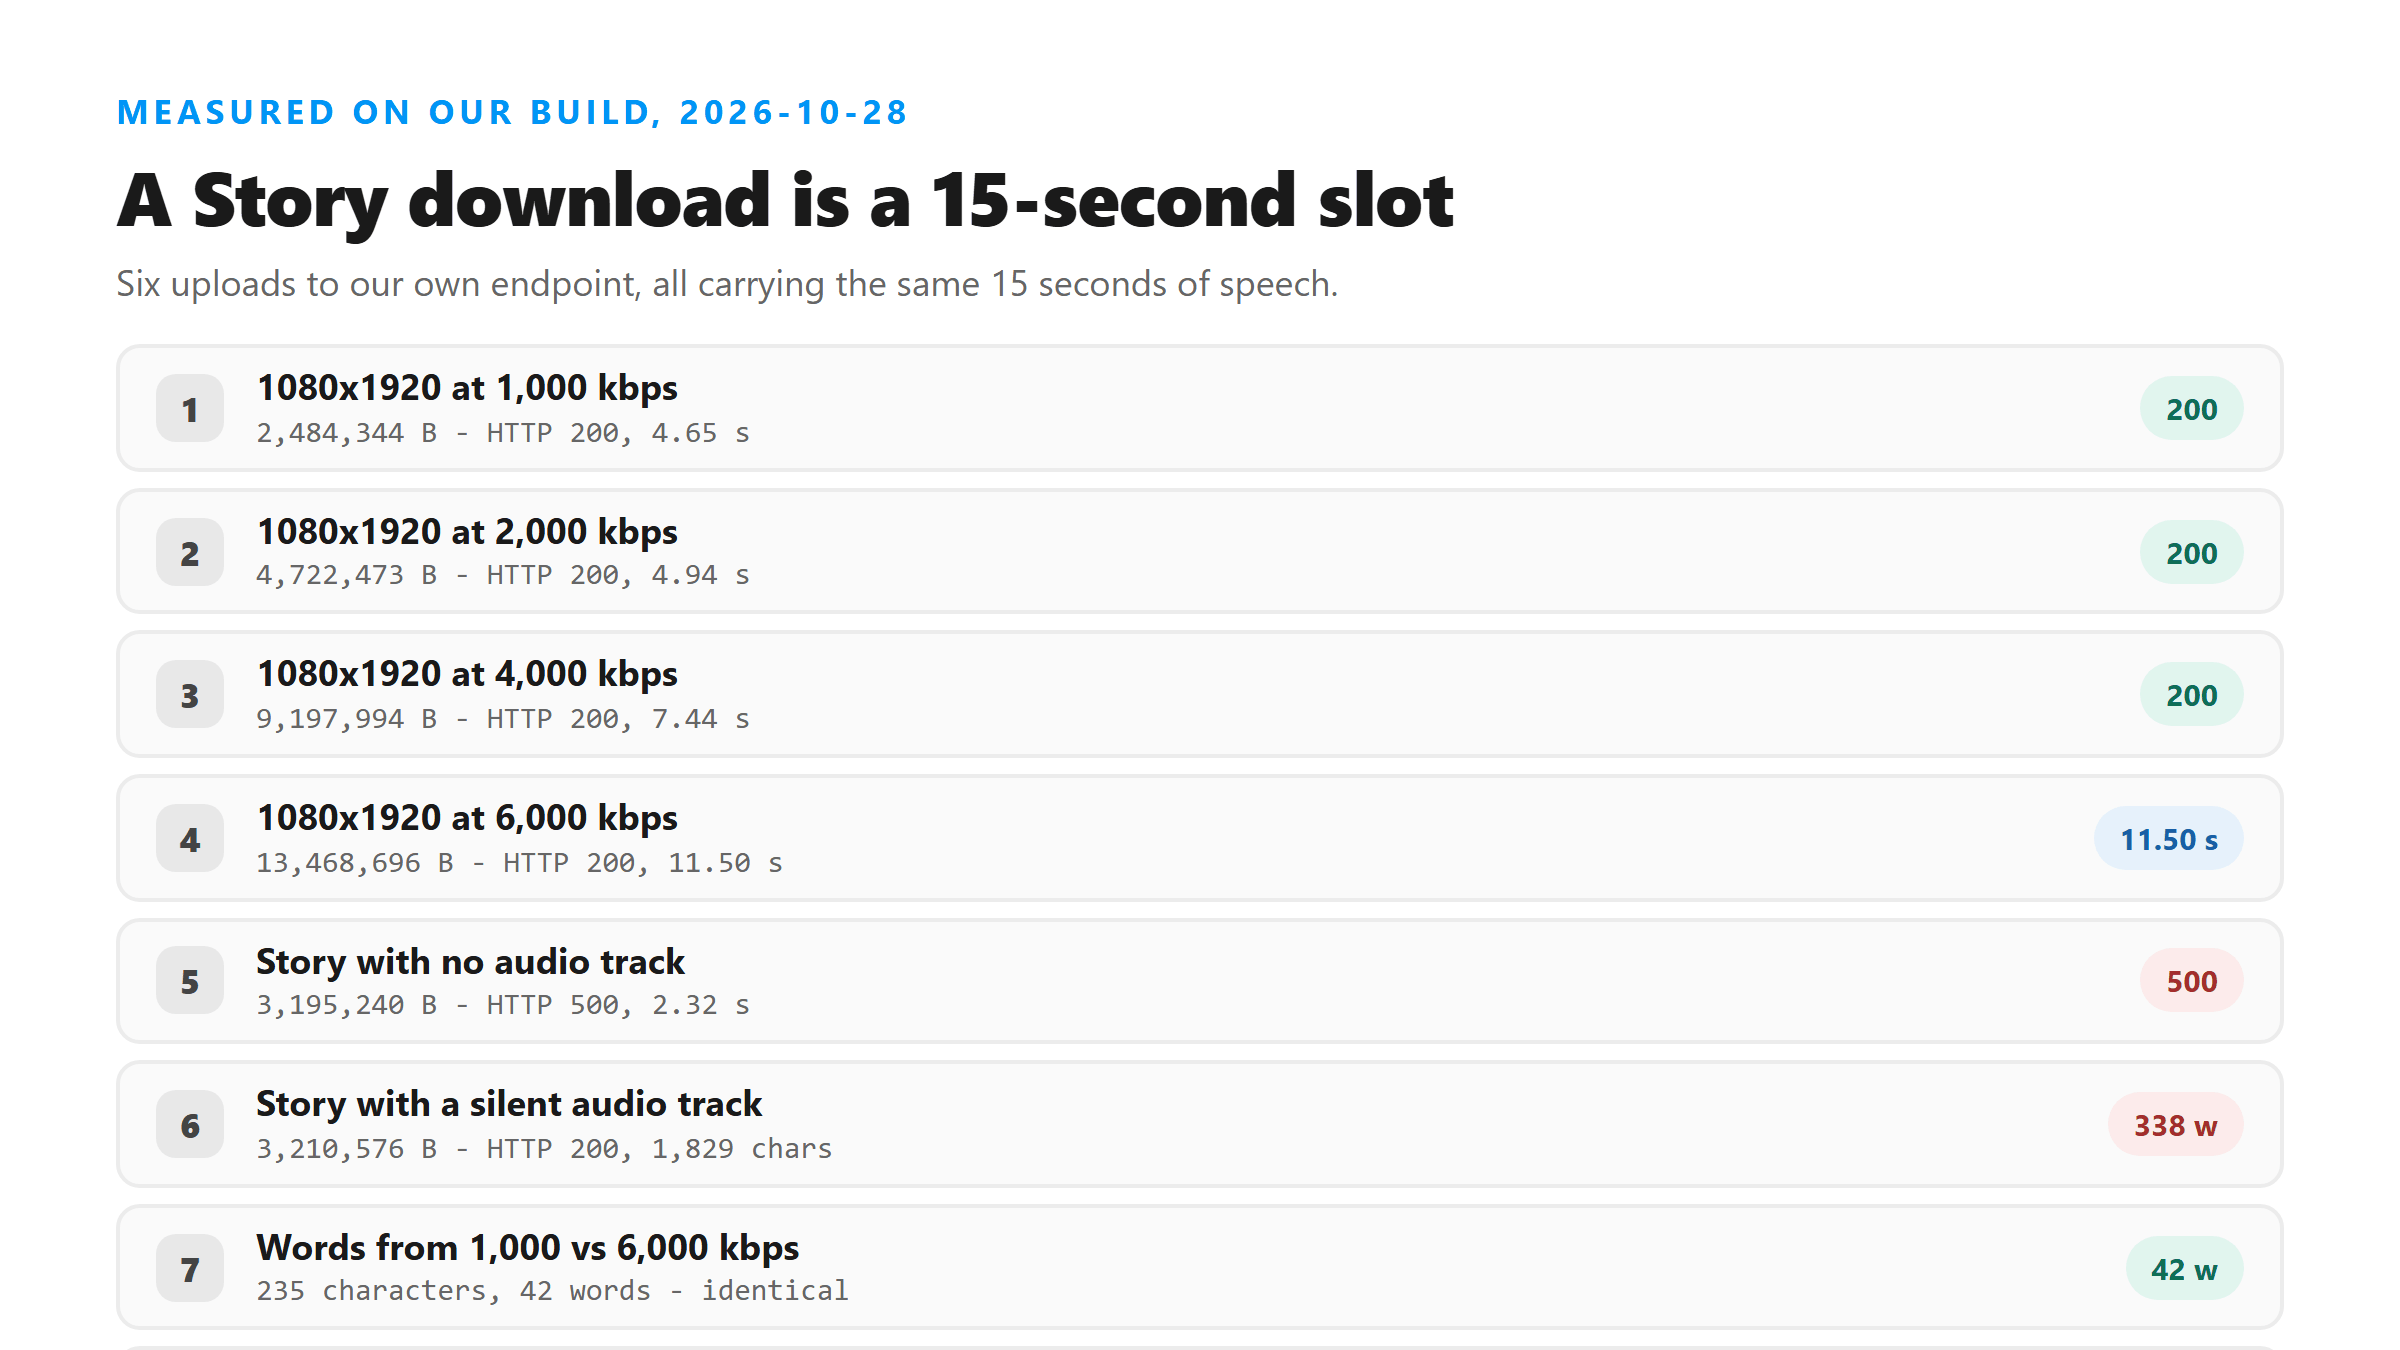
We built four 15-second Story-shaped files, each carrying the same speech, and uploaded them to our own endpoint. The bitrate dial moved the size by a factor of five. It did not move a single word.
- 1,000 kbps - 2,484,344 bytes, HTTP 200 in 4.65 seconds, 235 characters and 42 words.
- 2,000 kbps - 4,722,473 bytes, HTTP 200 in 4.94 seconds, 235 characters and 42 words.
- 4,000 kbps - 9,197,994 bytes, HTTP 200 in 7.44 seconds, 235 characters and 42 words.
- 6,000 kbps - 13,468,696 bytes, HTTP 200 in 11.50 seconds, 235 characters and 42 words.
The two ways a Story download breaks
Neither failure has anything to do with resolution. Both are about the audio track, and they behave in opposite ways. One refuses the file outright. The other accepts it and writes a page of text nobody said.
- No audio track at all: 3,195,240 bytes, HTTP 500 in 2.32 seconds. The endpoint never got a waveform to read.
- A silent audio track: 3,210,576 bytes, HTTP 200 in 14.92 seconds, and 1,829 characters across 338 words. Same length, same shape, and the model filled the silence with a repeated phrase.
- That second one is the dangerous case. It comes back with success:true and no warning field, so nothing on the page tells you the words were invented.
Check the file before you upload it
One command tells you which of the two failures you are about to hit. Run ffprobe -v error -select_streams a -show_entries stream=codec_name -of json yourfile.mp4. If it prints an empty list, there is no audio stream and the upload will fail with a 500. If it prints a stream, the upload will succeed - and then you have to judge the output yourself, because a silent track still counts as a stream.
What comes back from a Story
The response has six fields: success, transcript, language, engine, fileSize and fileName. There is no timestamp, no speaker label and no confidence score. Our 15-second Story came back as one unbroken run of text with zero newlines in it. If you need to know where in the clip something was said, the transcript will not tell you, and the SRT export writes a single cue running 00:00:00,000 to 00:00:00,000.
Where that leaves you
Download the smallest version you can live with, because size buys you nothing but wait time. Then check for an audio stream before you upload, and read the first line of the result before you trust it. If the text is far longer than the clip deserves, you are looking at invented output. Our silent file produced 338 words out of 15 seconds, which is roughly 22 words a second.
Got a Reel you want as text? Upload the file and download the transcript as TXT, SRT, or VTT →
Bitrate is the only dial a downloader gives you, and today it changed nothing but the wait. Wondershare UniConverter opens the Story file on your own machine and writes the audio out on its own, which is the 199,803-byte version of a 15-second clip instead of the 13.5 MB one. It does not transcribe - the words come back from this page.
FAQ
Does downloading a Story at a higher quality give a better transcript?
No. We ran 1,000 kbps through 6,000 kbps on the same 15 seconds of speech and every file returned the same 235 characters and 42 words. Higher bitrate only makes the file bigger and the upload slower.
Why did my Story download fail with HTTP 500?
Almost always because the file has no audio stream. A Story that was posted as a still image can be saved as a video with no audio track in it, and there is nothing for the model to read. Run ffprobe and check for an audio stream first.
My Story came back with hundreds of words but nobody says that in the clip.
That is the silent-track case. The file has an audio stream, so the upload succeeds, and the model fills the silence instead of returning nothing. Ours produced 1,829 characters and 338 words from 15 seconds of silence.