Surround Audio to Text: When the Voice Isn't in the Center Channel
Why this test exists
Surround recordings turn up more often than you would expect. A phone that recorded in 5.1 by accident, a camera that wrote six channels, a screen capture from a laptop with a surround output. The obvious question is whether the extra channels help or hurt. The answer depends entirely on which channel the voice landed in.
How the four layouts were built
One source file, 50.86 seconds of mono speech. We panned it into a 5.1 layout four different ways with ffmpeg, then wrote each to a 48 kHz six-channel WAV. Each one went out as an MP4 with AAC at 192 kbps and a black video track. Every file had six channels and the same duration. Only the routing differed.
The four results
Three layouts are indistinguishable from a plain mono upload. The fourth is a different kind of output altogether.
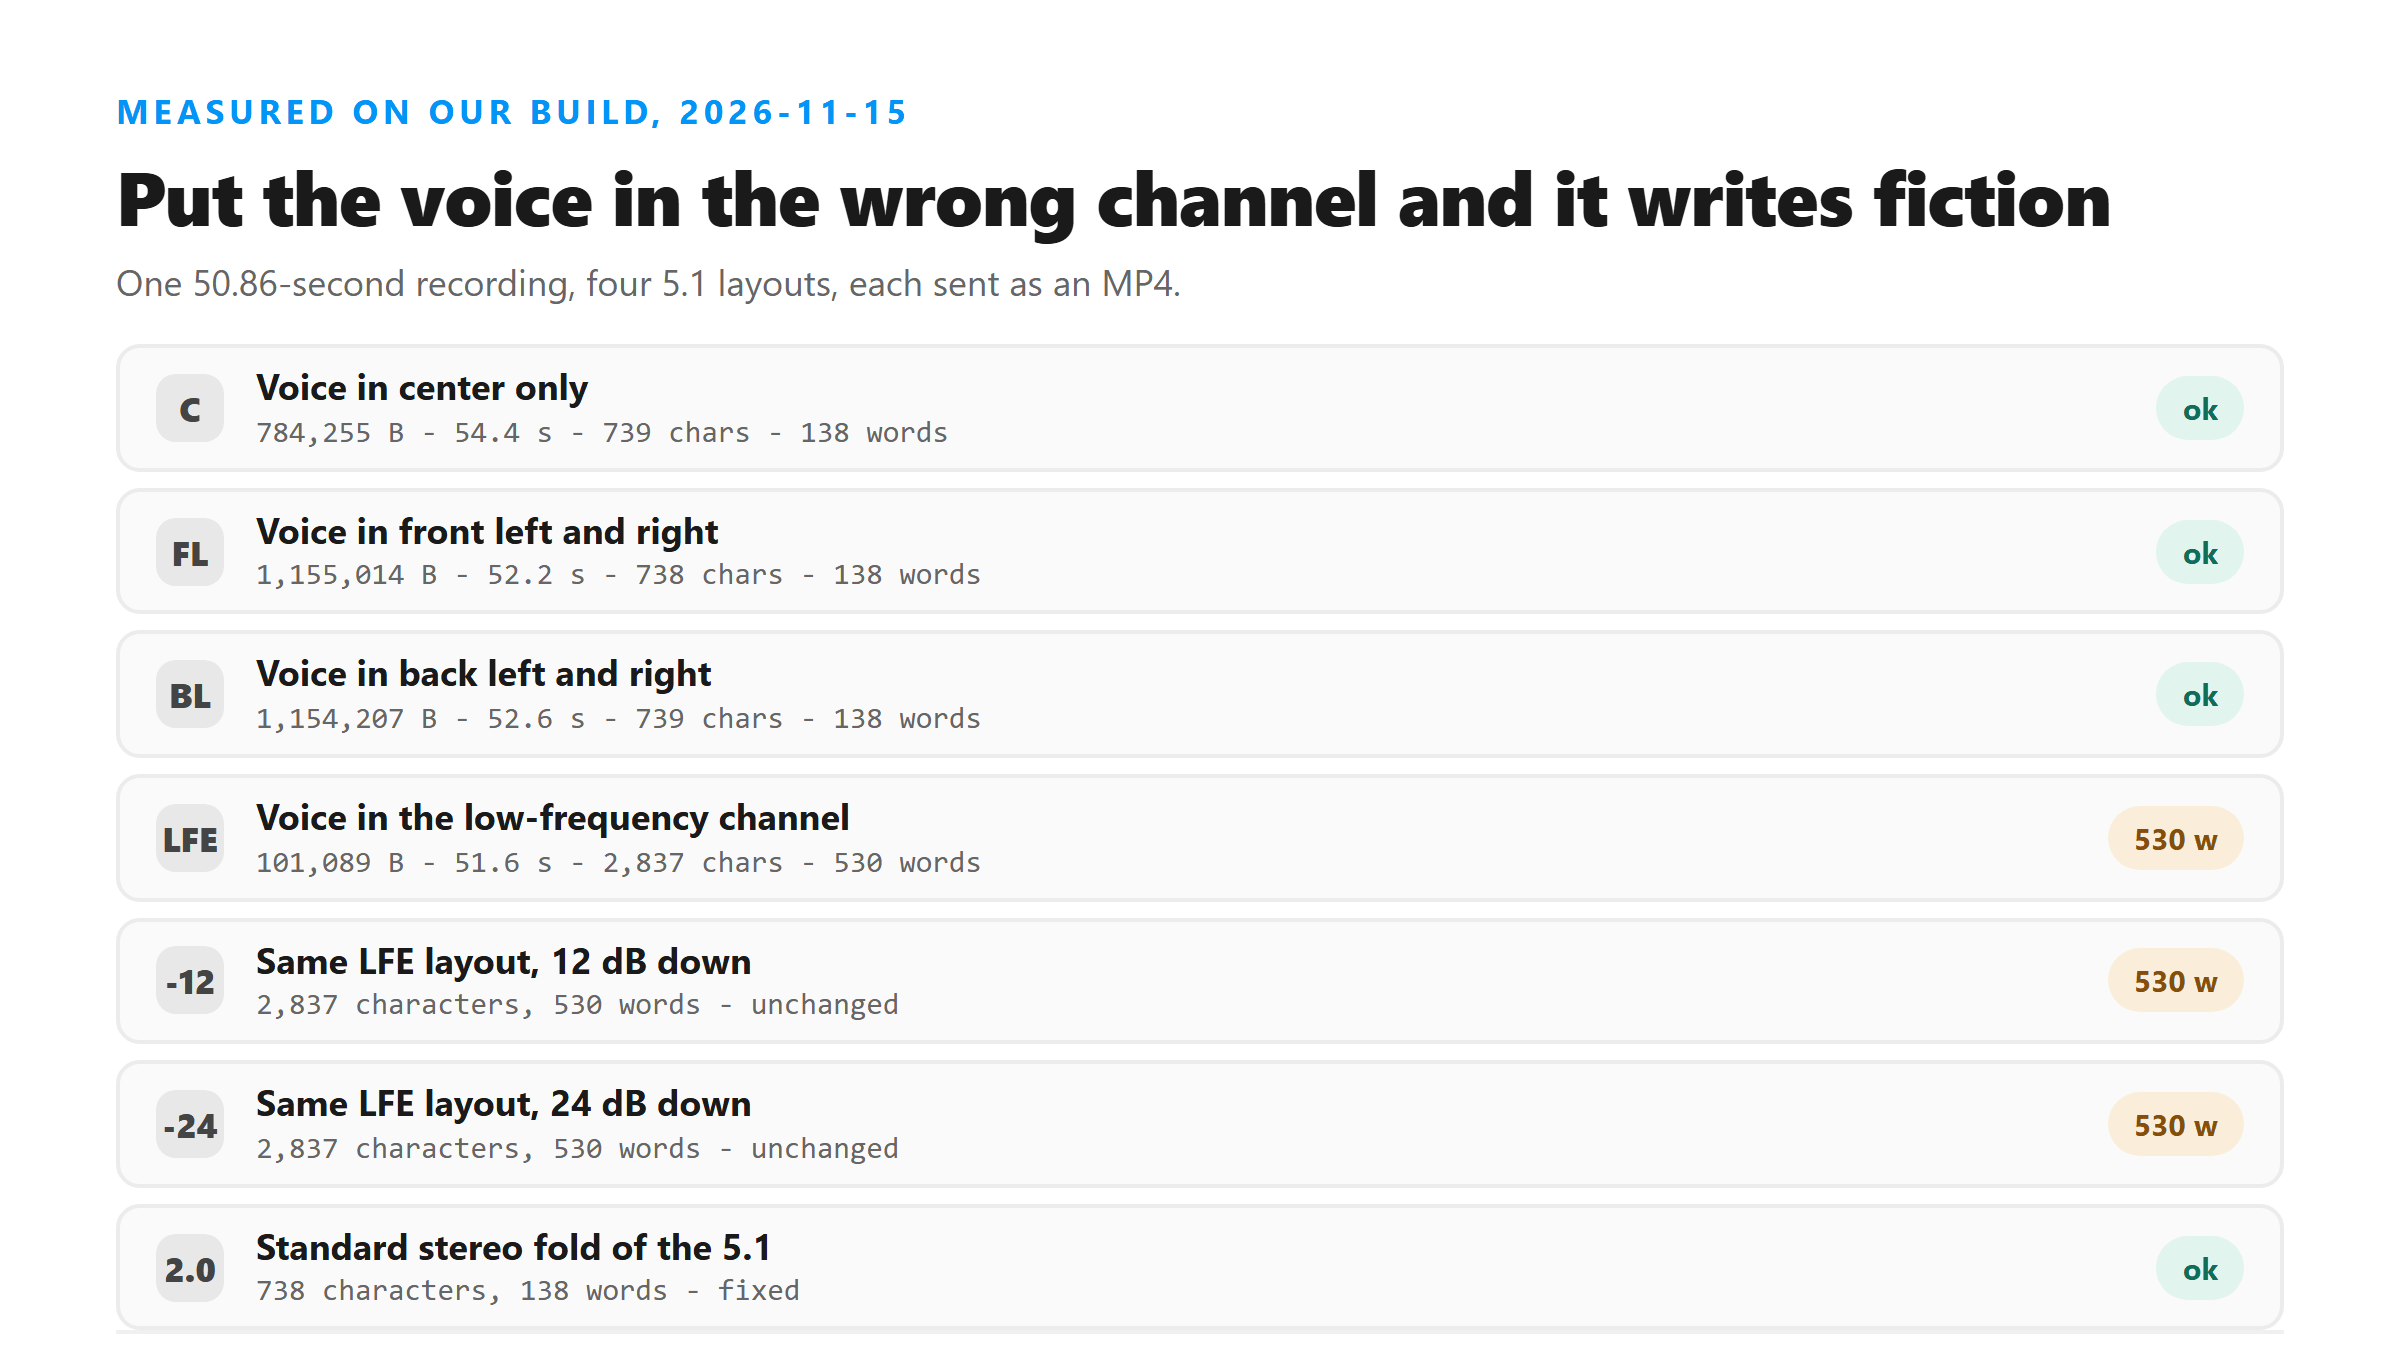
- Voice in C only - 784,255 bytes - 54.4 s - 739 characters - 138 words
- Voice in FL and FR - 1,155,014 bytes - 52.2 s - 738 characters - 138 words
- Voice in BL and BR - 1,154,207 bytes - 52.6 s - 739 characters - 138 words
- Voice in LFE only - 101,089 bytes - 51.6 s - 2,837 characters - 530 words
The first line is the shape of a correct answer. The last line is not a worse transcript, it is a fabricated one: Thank you very much, over and over, for the length of the file.
Lowering the level did not change it
The natural guess is that a too-loud low-frequency channel confused the model. So we rebuilt the same layout at -12 dB and -24 dB and sent both. Characters: 2,837, 2,837, 2,837. Words: 530, 530, 530. Level was not the variable.
What a normal downmix does
Real playback does not hear six channels separately. It folds them into two: front left, front right, center, and the surrounds at reduced level, with the low-frequency channel usually dropped. We made that fold explicitly - a standard 2.0 downmix of the same 5.1 file - and it returned 738 characters and 138 words. Adding the center channel to the LFE file also fixed it: 739 and 138. Voice plus back channels: 739 and 138.
The mistake worth avoiding
Say an editor lets you pick channels one at a time, and you pick the wrong one. You can hand the endpoint a channel with almost nothing in it. What comes back will look like an answer: right length, fluent English, no error code. The tell is repetition. A transcript that says the same short sentence dozens of times is not a bad recording. It is a model with no signal to read.
The size is the second tell, and it is the one that would have caught us. A 101 KB file that returns twenty times the text of a 784 KB file is not doing more work. It is doing less and making it up.
What to do with a surround file
Downmix to stereo or mono first. ffmpeg -i clip.mp4 -ac 2 -ar 44100 out.wav does the standard fold and takes well under a second for a clip this length. If you keep the surround version, keep it for listening and send the fold for text.
The limits of this test
One recording, four layouts, one endpoint, 50.86 seconds. We did not test a genuine film mix where dialogue sits in the center and music sits in the surrounds, which is the case people actually hit. We also did not test a 7.1 layout or a file with six discrete microphones rather than a panned mono source. The finding is about routing, not about surround sound in general.
What happens to your file
The MP4 is decoded in memory and not stored. The channel routing happened locally with ffmpeg before the upload, so the server never saw six-channel source material.
Got a Reel you want as text? Turn the Reel into an Instagram transcript you can download →
A six-channel file that folds cleanly to two is the shape transcription handles best. Wondershare UniConverter exports a stereo file from a surround source at a peak you choose, which is the downmix our 784,255-byte center-channel run needed. It does not transcribe - the words come back here.
FAQ
Does 5.1 audio work for transcription?
Yes, if the voice is in a channel that a normal downmix keeps. Center, front pair and back pair all returned 738 or 739 characters in our runs. A voice that exists only in the low-frequency channel did not.
Why did my transcript repeat the same sentence over and over?
That is what our LFE-only file produced: 2,837 characters of Thank you very much. It is the shape of a model reading a channel with no speech in it. Check which channel your voice is actually on before blaming the audio.
Should I convert surround to stereo before uploading?
Yes. A standard two-channel fold returned the same 738 characters as the layout with the voice in the center, and the file gets much smaller. There is nothing in the extra channels that helps the text.
Can a small file give a long transcript?
It can, and that is a warning sign rather than good news. Our 101,089-byte LFE file returned 530 words from 51.6 seconds, against 138 words from files seven times its size.