A Clip With Music Only: What Comes Back
The same 15 seconds, three times
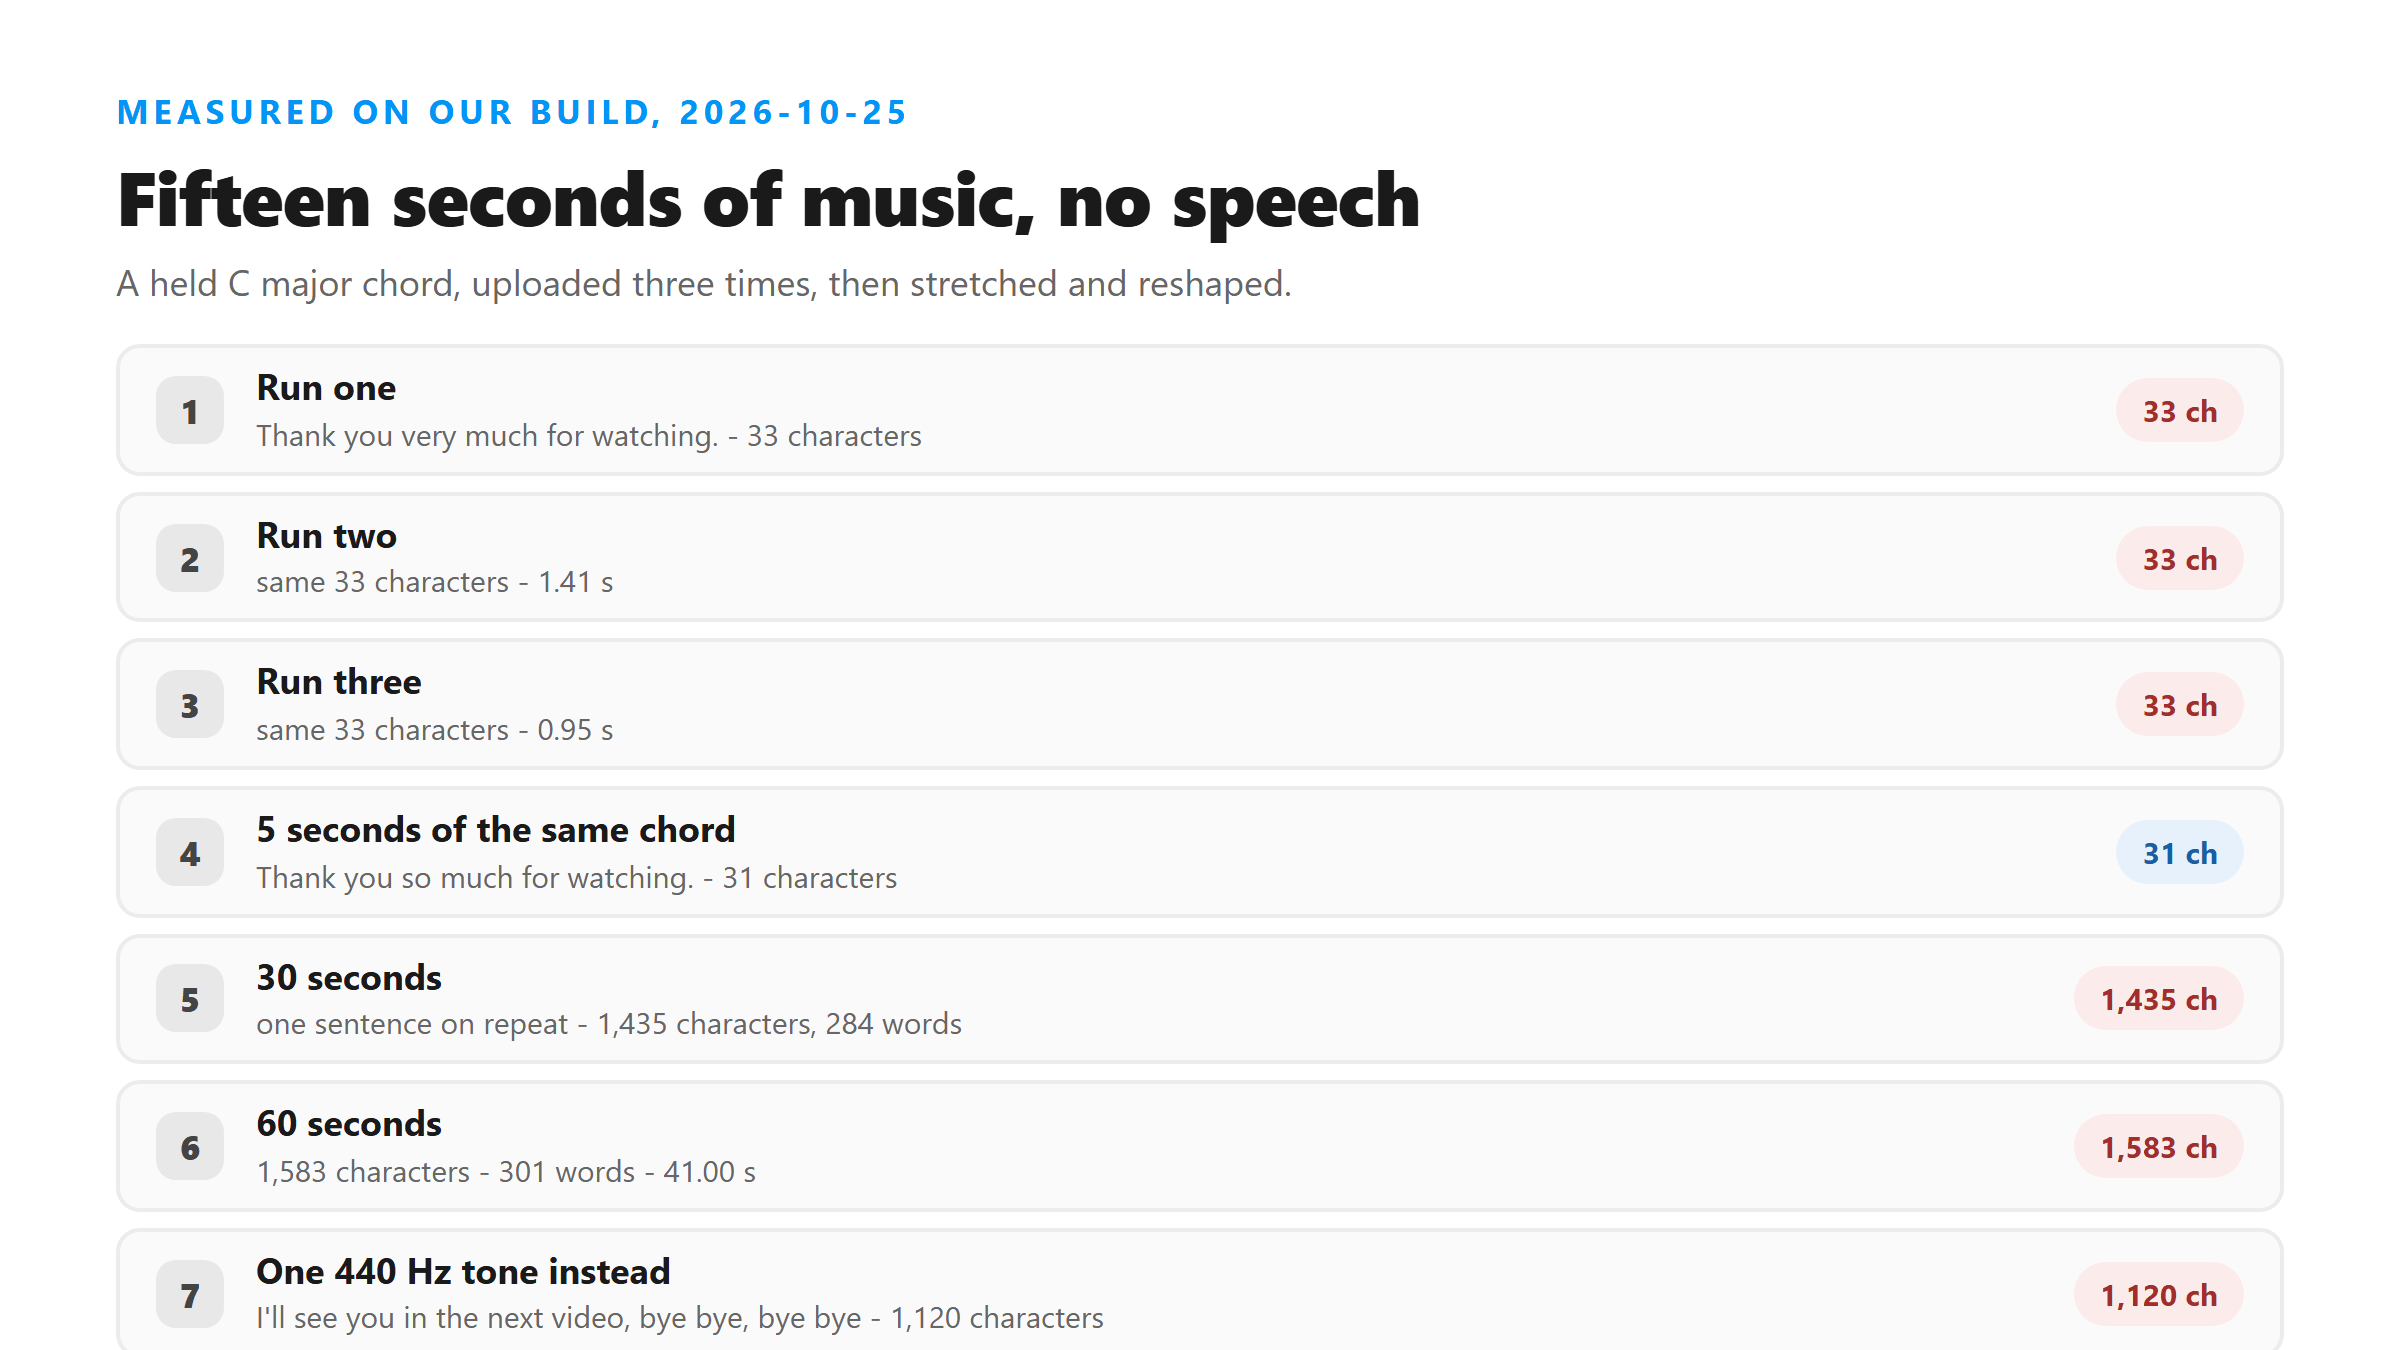
One file, a C major chord held for 15 seconds, uploaded three times.
- First run: 33 characters, 6 words, 1.49 s
- Second run: 33 characters, 6 words, 1.41 s
- Third run: 33 characters, 6 words, 0.95 s
Identical text each time. So re-running will not save you here - the hallucination is as stable as a real transcript is. The wall clock moved by half a second across the three runs while the words stayed put.
Length is where it falls apart
We held the same chord for 5, 15, 30 and 60 seconds and sent all four.
- 5 s: 31 characters, 6 words, 0.83 s - "Thank you so much for watching."
- 15 s: 33 characters, 6 words, 1.49 s - "Thank you very much for watching."
- 30 s: 1,435 characters, 284 words, 11.99 s
- 60 s: 1,583 characters, 301 words, 41.00 s
The 30- and 60-second results are one sentence repeated until the file runs out - "This is the first time I've ever been to a place like this, where I've never seen a place like this..." over and over. Sixty seconds of music took 41 seconds to process and came back with 301 words that nobody said.
Not every kind of music behaves the same
Four kinds of sound, 15 seconds each, no speech in any of them.
- Three-note chord: 33 characters, 6 words, 1.49 s - "Thank you very much for watching."
- Single 440 Hz tone: 1,120 characters, 225 words, 9.61 s - "I'll see you in the next video, bye bye, bye bye..."
- Gated noise beat: 444 characters, 1 word, 7.94 s - one repeated "M-M-M-M-" token
- Bass with a vibrato melody: 34 characters, 7 words, 1.34 s - "Thank you very much for your time."
A steady tone was the worst of the four by a wide margin: 1,120 characters against 33. A steady chord and a melody both came back with a single polite sign-off.
Turning it down does not help
We changed the level on the same 15-second chord and re-sent it.
- -30 dB: 20 characters, 3 words, 1.23 s - "Thanks for watching!"
- -12 dB: 20 characters, 4 words, 1.00 s - "Thank you very much."
- +6 dB: 33 characters, 6 words, 1.06 s - "Thank you very much for watching."
Quieter music gets a shorter answer, not a truer one. There is no level at which the model admits it heard nothing.
One case where the music stays quiet
We put 13 seconds of the chord in front of 2 seconds of real Spanish speech - the shape of a clip with a music intro. The response was 13 characters and 3 words: "Hola a todos." The music added nothing at all. Real speech after music does not pick up a junk prefix, so an intro is not what breaks a clip. Music with no speech anywhere in it is.
How to tell it is fake
Two checks that worked today. First, characters per second: real speech ran 15 to 17 characters per second across a length ladder we ran today, while the 30-second music clip ran 47.8 - three times the words for the same length. Second, read it. Every music result today was one short sentence, or one short sentence repeated. If the whole transcript is a sign-off, there was nothing to transcribe.
Re-encoding will not shake it loose either. The same 15 seconds came back as the same 33 characters in MP3 at 64 kbps and in a 1.3 MB WAV. Dropping to 8 kHz did change it - 70 characters instead of 33 - because downsampling feeds the model different audio, not because it exposes the problem.
Got a Reel you want as text? Upload the file and download the transcript as TXT, SRT, or VTT →
Nothing on this page is fixed by changing the file: the same 15 seconds came back as the same 33 characters in three containers and at three volumes. Where Wondershare UniConverter does help is the clip you actually want words from — it cuts the music bed down or splits it off before you upload, which is the only change that moves the output.
FAQ
What comes back from a clip with only music?
Text that nobody said. Today 15 seconds of a synthesized chord returned "Thank you very much for watching." - 33 characters, 6 words - with success: true and no warning field. Three uploads gave the same 33 characters.
Does a longer music clip come back worse?
Yes. Today 5 seconds gave 31 characters, 15 seconds gave 33, 30 seconds gave 1,435 and 60 seconds gave 1,583 characters in 41.00 seconds. The longer ones are one sentence repeated until the audio runs out.
Can I fix it by re-encoding or lowering the volume?
No. The same 15 seconds returned the same 33 characters as MP3 at 64 kbps and as a 1.3 MB WAV. Turning it down to -30 dB only shortened the answer to "Thanks for watching!" - 20 characters instead of 33.
Does music before someone speaks cause the same problem?
No. We put 13 seconds of music in front of 2 seconds of real speech and got 13 characters back - just the speech. Music with no speech anywhere in the file is what produces the fake sign-off.